2.3 KiB


"The Greatest Path is the Simplest"
-
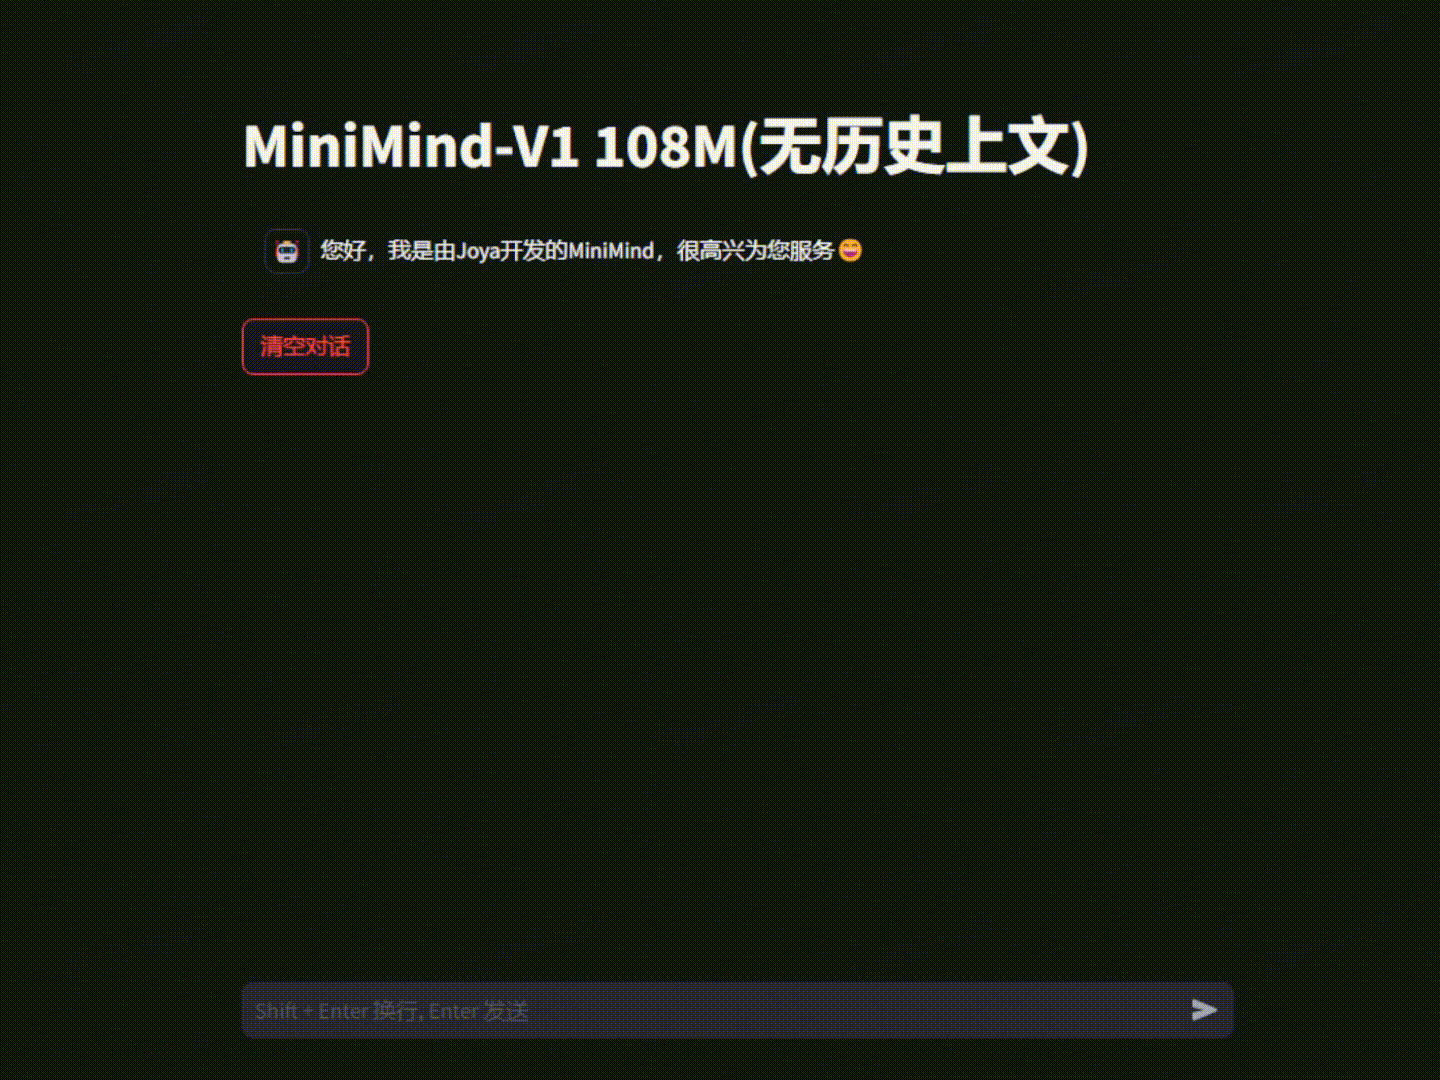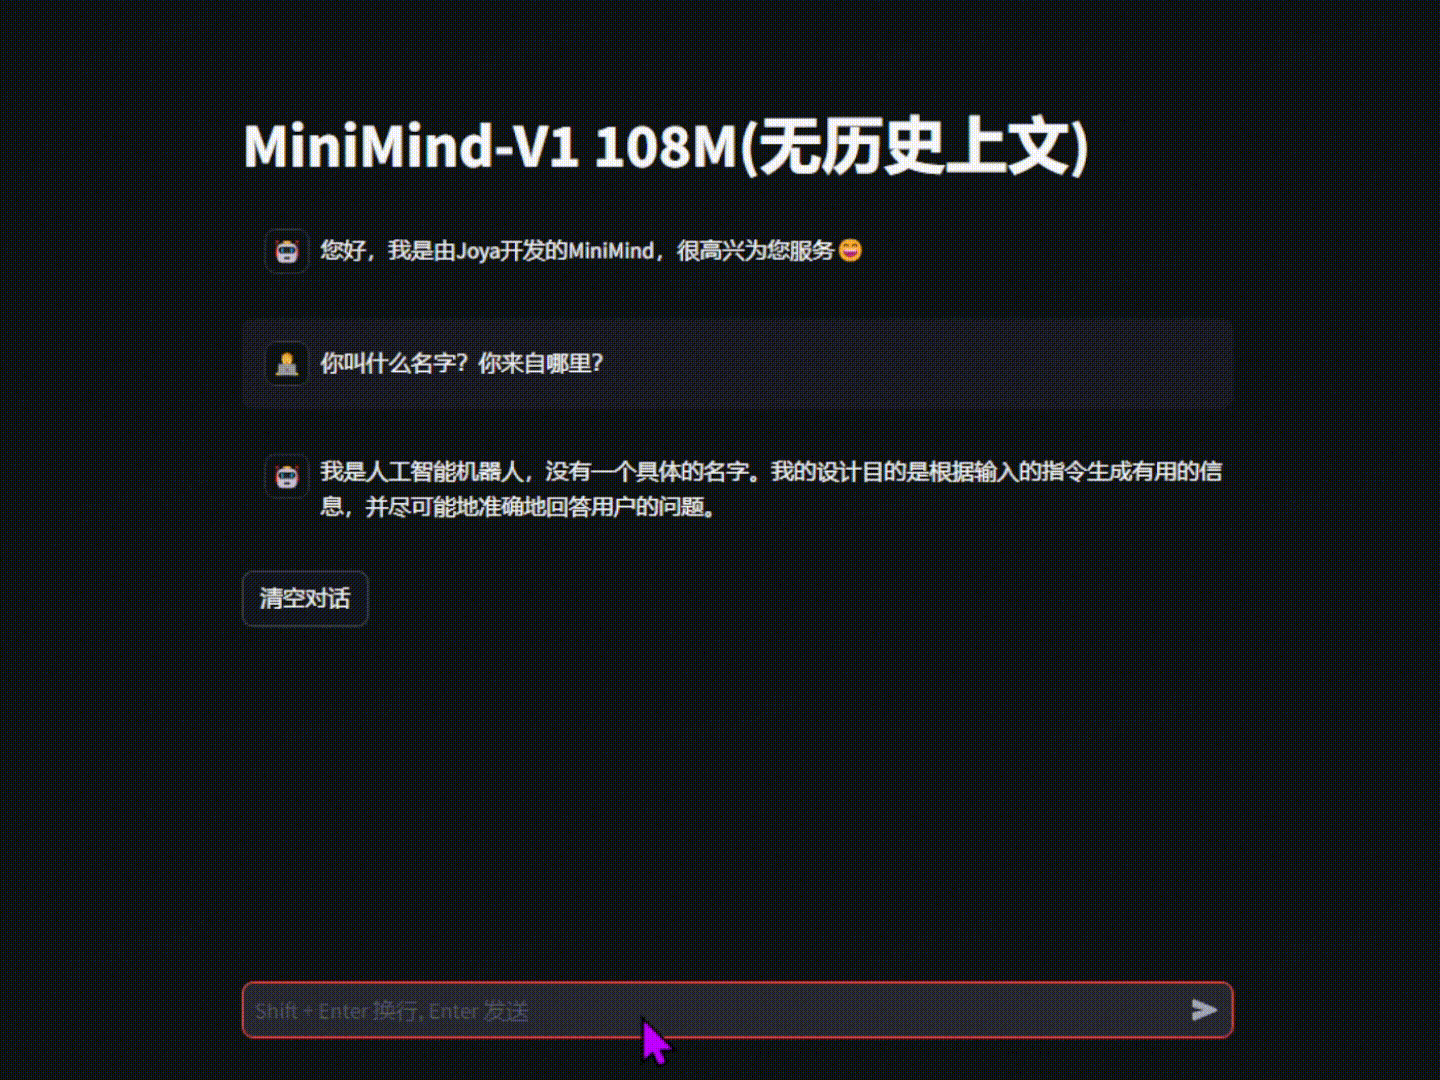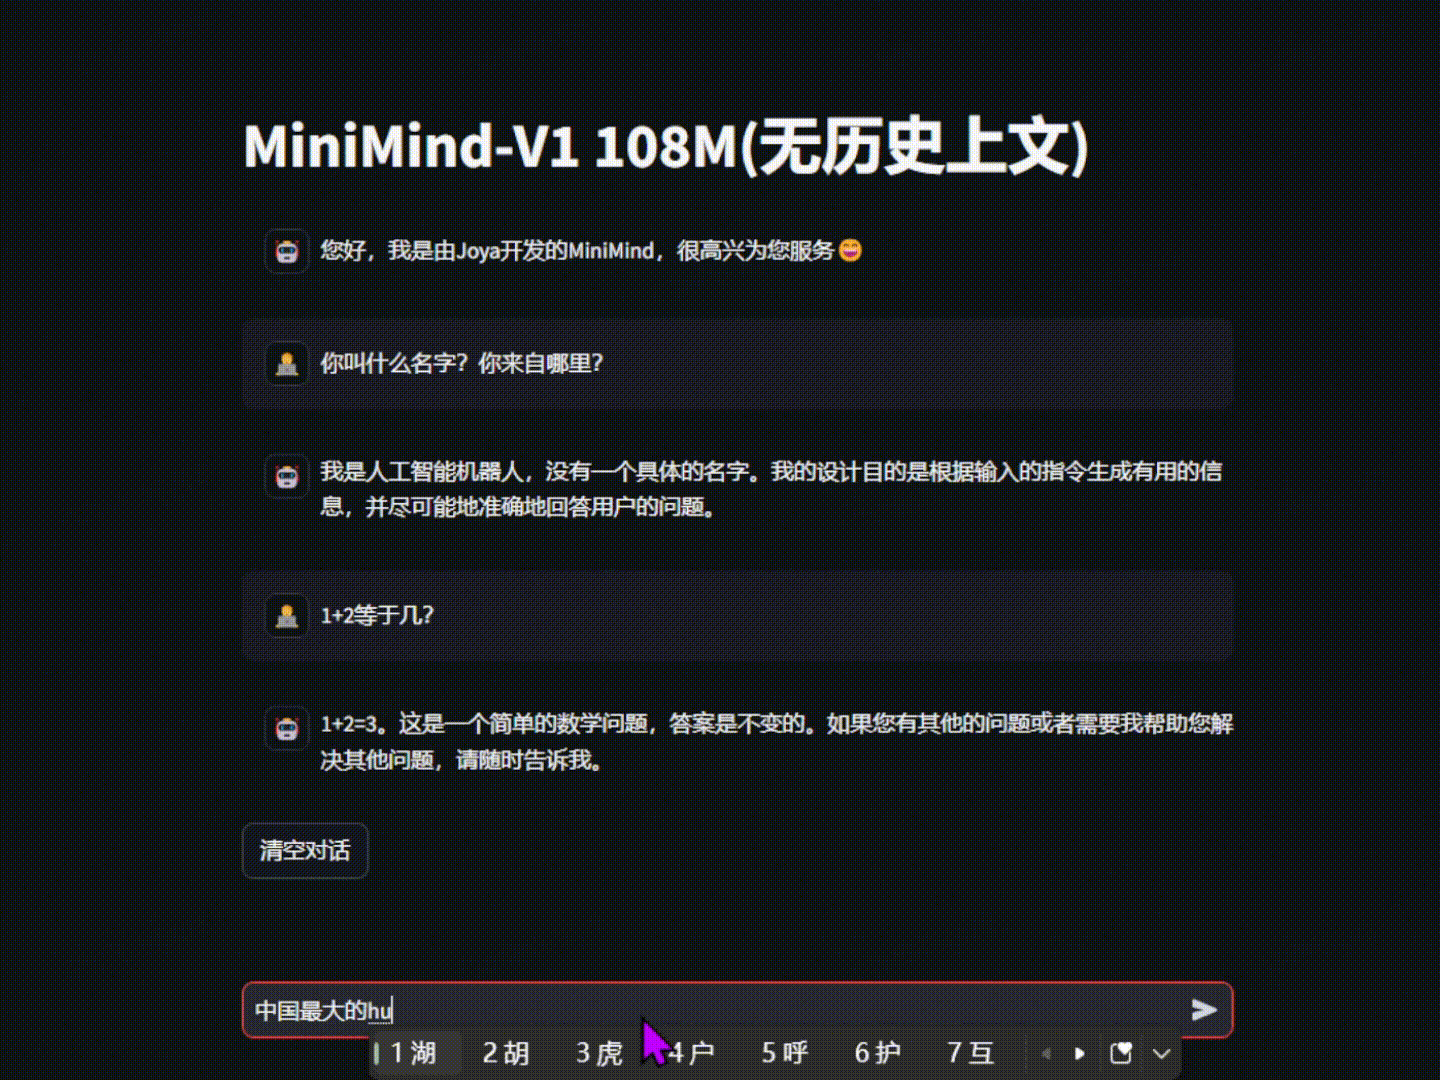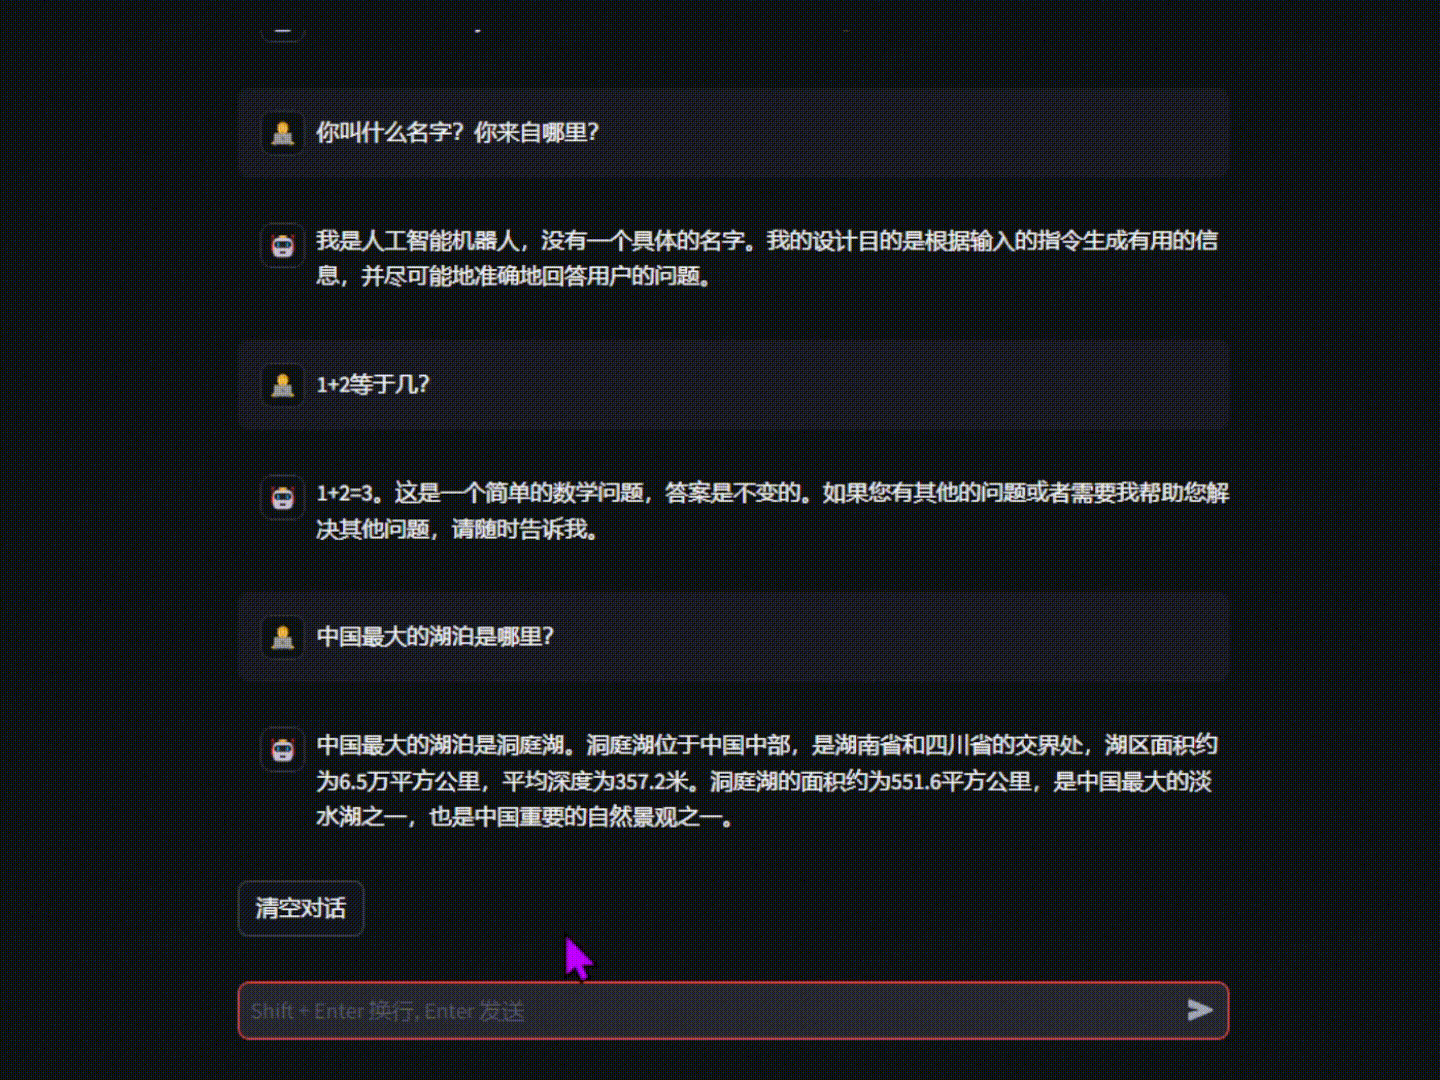
This open-source project aims to train a tiny language model called MiniMind from scratch in just 3 hours, with a model size of only 26.88M.
-
MiniMind is extremely lightweight, with the smallest version being approximately
\frac{1}{7000}the size of GPT3, making it possible for even an ordinary personal GPU to perform quick inference and even training. -
MiniMind provides the full-stage code for a simplified large model structure, dataset cleaning and preprocessing, supervised pretraining, supervised instruction fine-tuning (SFT), low-rank adaptation (LoRA) fine-tuning, and direct preference alignment with reinforcement learning without rewards (DPO). It also includes code for expanding to sparse models with mixed experts (MoE) and multi-modal vision language models (VLM): MiniMind-V.
-
This is not just an implementation of an open-source model but also a tutorial for getting started with large language models (LLM).
-
We hope this project will serve as an introductory example for researchers, helping them quickly get started and inspiring more exploration and innovation in the LLM field.
To avoid misinterpretation, "fastest 3 hours" means you need a machine with hardware configuration superior to mine. Detailed specifications will be provided below.